Loading...
← All work
Case study · JobAiroDelivered
Going straight to the source to build a job search that stays current.
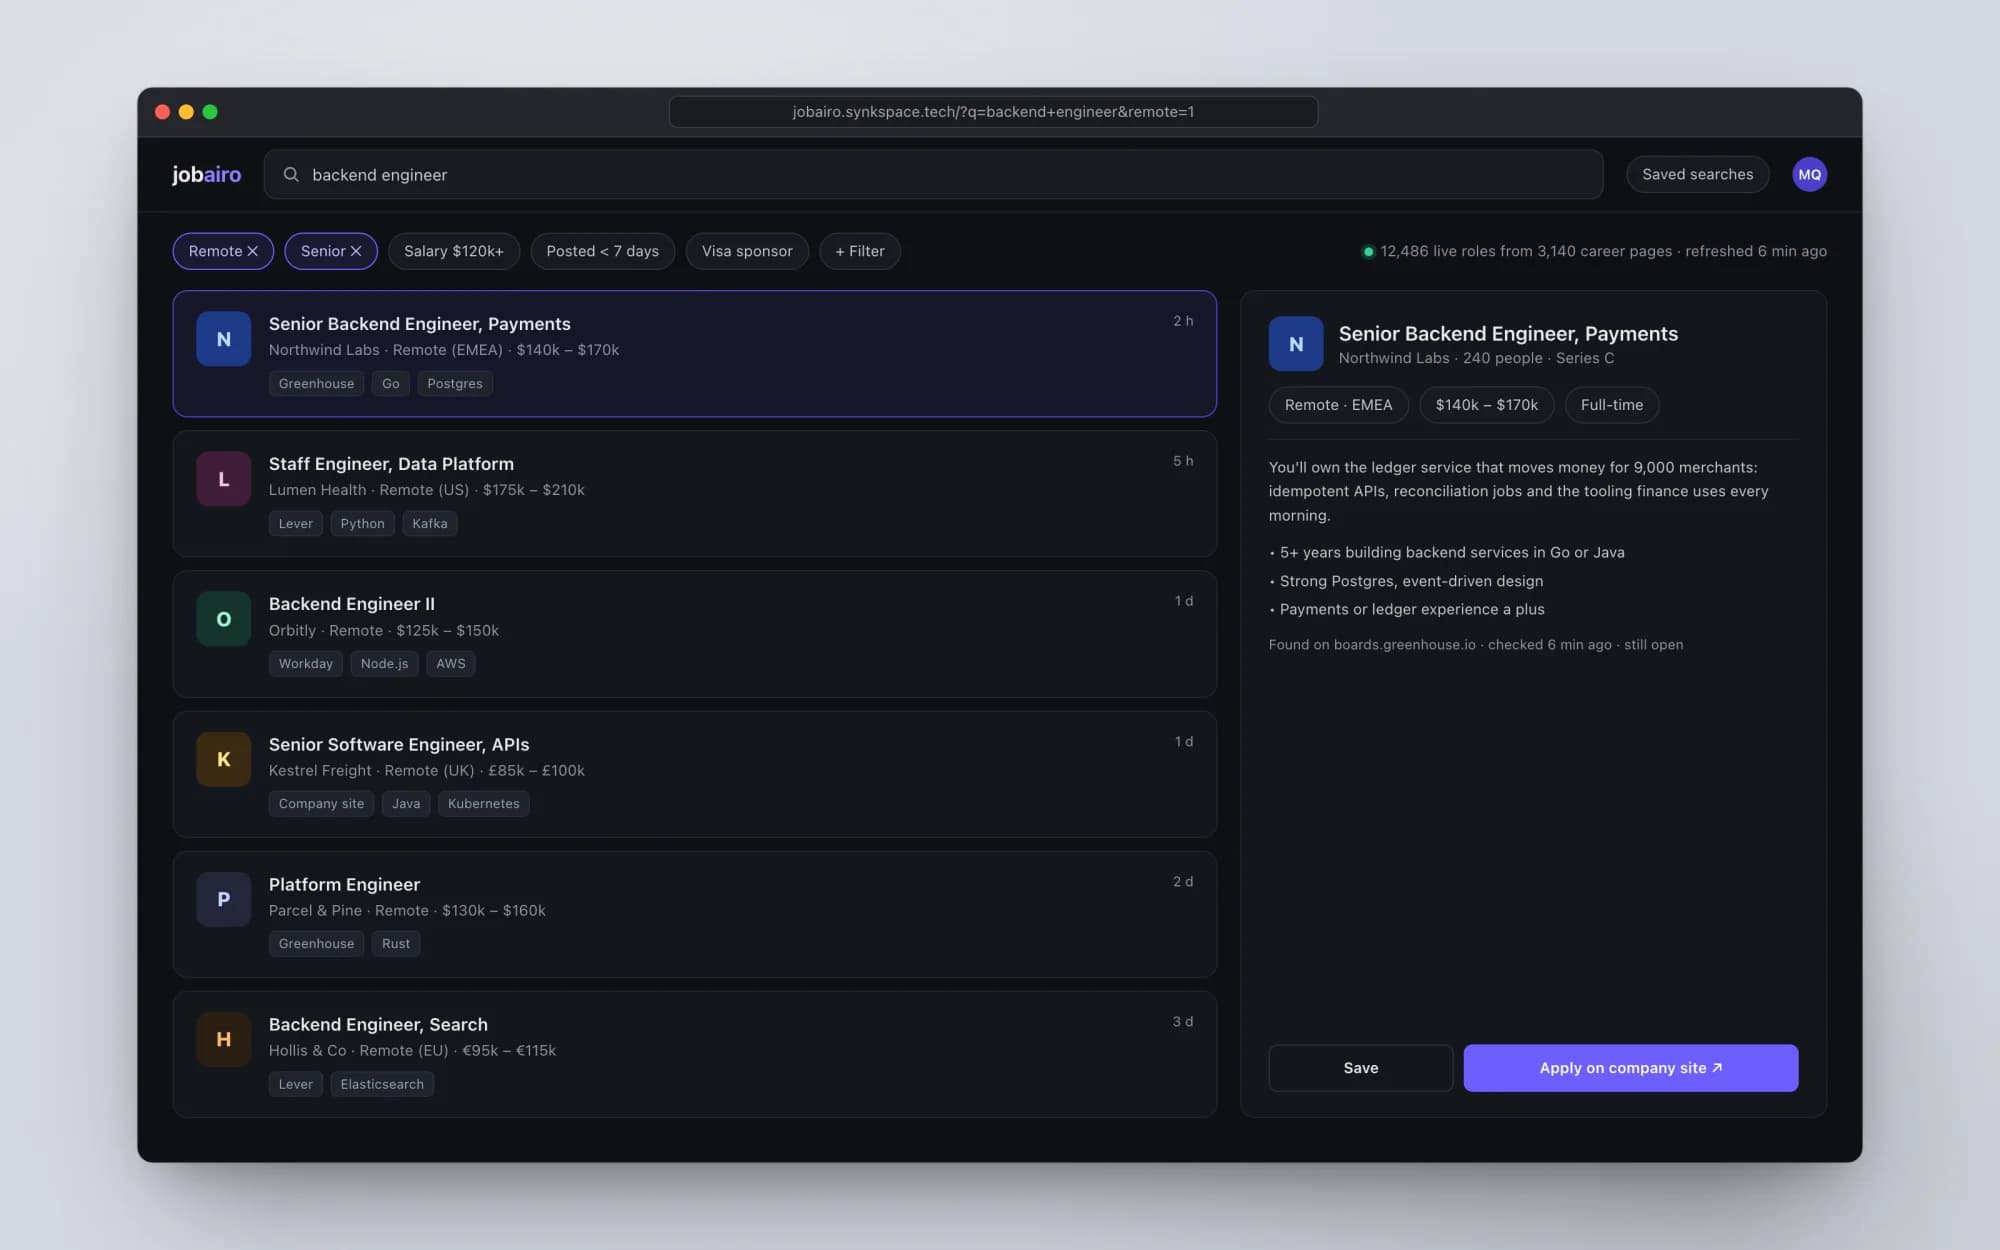
A job search engine that finds companies’ own career pages, reads openings from Greenhouse, Lever, Workday and custom sites, and serves them in one fast, filterable search.
- Sector
- Recruitment & HR Tech
- Our role
- Distributed scraping, data pipeline, search product
- Capabilities
- Automation · Platforms
- Status
- Delivered
The challenge
Job boards are full of stale and duplicated posts.
Job boards are full of stale and duplicated posts. The freshest data sits on companies’ own career pages, spread across a dozen hiring systems. JobAiro goes to the source and keeps it current.
What made it hard
- 01
Heterogeneous sources
Openings live on thousands of career pages, across Greenhouse, Lever, Workday and custom builds.
- 02
Schema chaos
Every platform structures titles, locations and salary differently.
- 03
Freshness at scale
Closed roles must disappear as fast as new ones appear, across every source, continuously.
The approach
A platform-aware router, async scrapers and one normalised schema.
A locator resolves each careers page and fingerprints its hiring platform. A router dispatches it to a dedicated adapter running on asyncio, with Selenium for JavaScript-heavy pages. Every result is normalised into one schema in Postgres, and stale roles are pruned on each pass.
System map
- AI step
- Person in the loop
- Service or store
How it works
- 01
Locate
A locator finds each company’s careers page and works out which hiring system it runs on.
- 02
Collect
A router hands it to the right scraper (Greenhouse, Lever, Workday or a generic fallback), running concurrently.
- 03
Normalise
Titles, locations, salary and stack are cleaned into one schema.
- 04
Store
Roles land in a hosted Postgres database, with closed roles dropped on the next pass.
- 05
Search
Candidates filter by remote, seniority, salary and recency, save searches and apply on the company site.
Key decisions
What keeps thousands of sources manageable.
Decision 01
One scraper per platform
Each hiring system gets its own adapter behind a router, so a site change breaks one adapter, not the pipeline.
Decision 02
Async by default
Pages are fetched concurrently, which is what makes thousands of sources practical.
Decision 03
Link out, don’t trap
Every role points to the company’s own application page, which keeps the data honest.
What shipped
A live job search, built from the source.
Platform fingerprinting
Finds each careers page and identifies the hiring system behind it.
Adapter-per-platform scrapers
Greenhouse, Lever, Workday and a generic fallback, run concurrently.
Schema normalisation
Titles, locations, salary and stack cleaned into one model.
Incremental sync
New roles upserted and closed roles dropped on every pass.
Faceted search
Remote, seniority, salary and recency filters, saved searches and direct apply.
Architecture
A cross-section of the system.
Every layer, from what people touch down to where it runs, and the one job each layer does.
L1Interface
Next.js+TypeScript+Tailwind
Fast faceted search over the normalised index.
L2Pipeline
Python+asyncio+Selenium
Concurrent, platform-specific scrapers behind a router.
L3Data
Supabase
Hosted Postgres holding the live, deduplicated role index.
Our scope
Data pipeline engineering/Distributed scraping/Search product/Web application
Where it is now
Delivered, and honest by design.
JobAiro is delivered. Every role deep-links to the company’s own application page, which keeps the data honest and the experience fair to employers.
Something like this in mind?
Tell us the problem. We will tell you honestly if we are the right team to solve it.