Loading...
← All work
Case study · Audient AIDelivered
Turning the consultation itself into the clinical record.
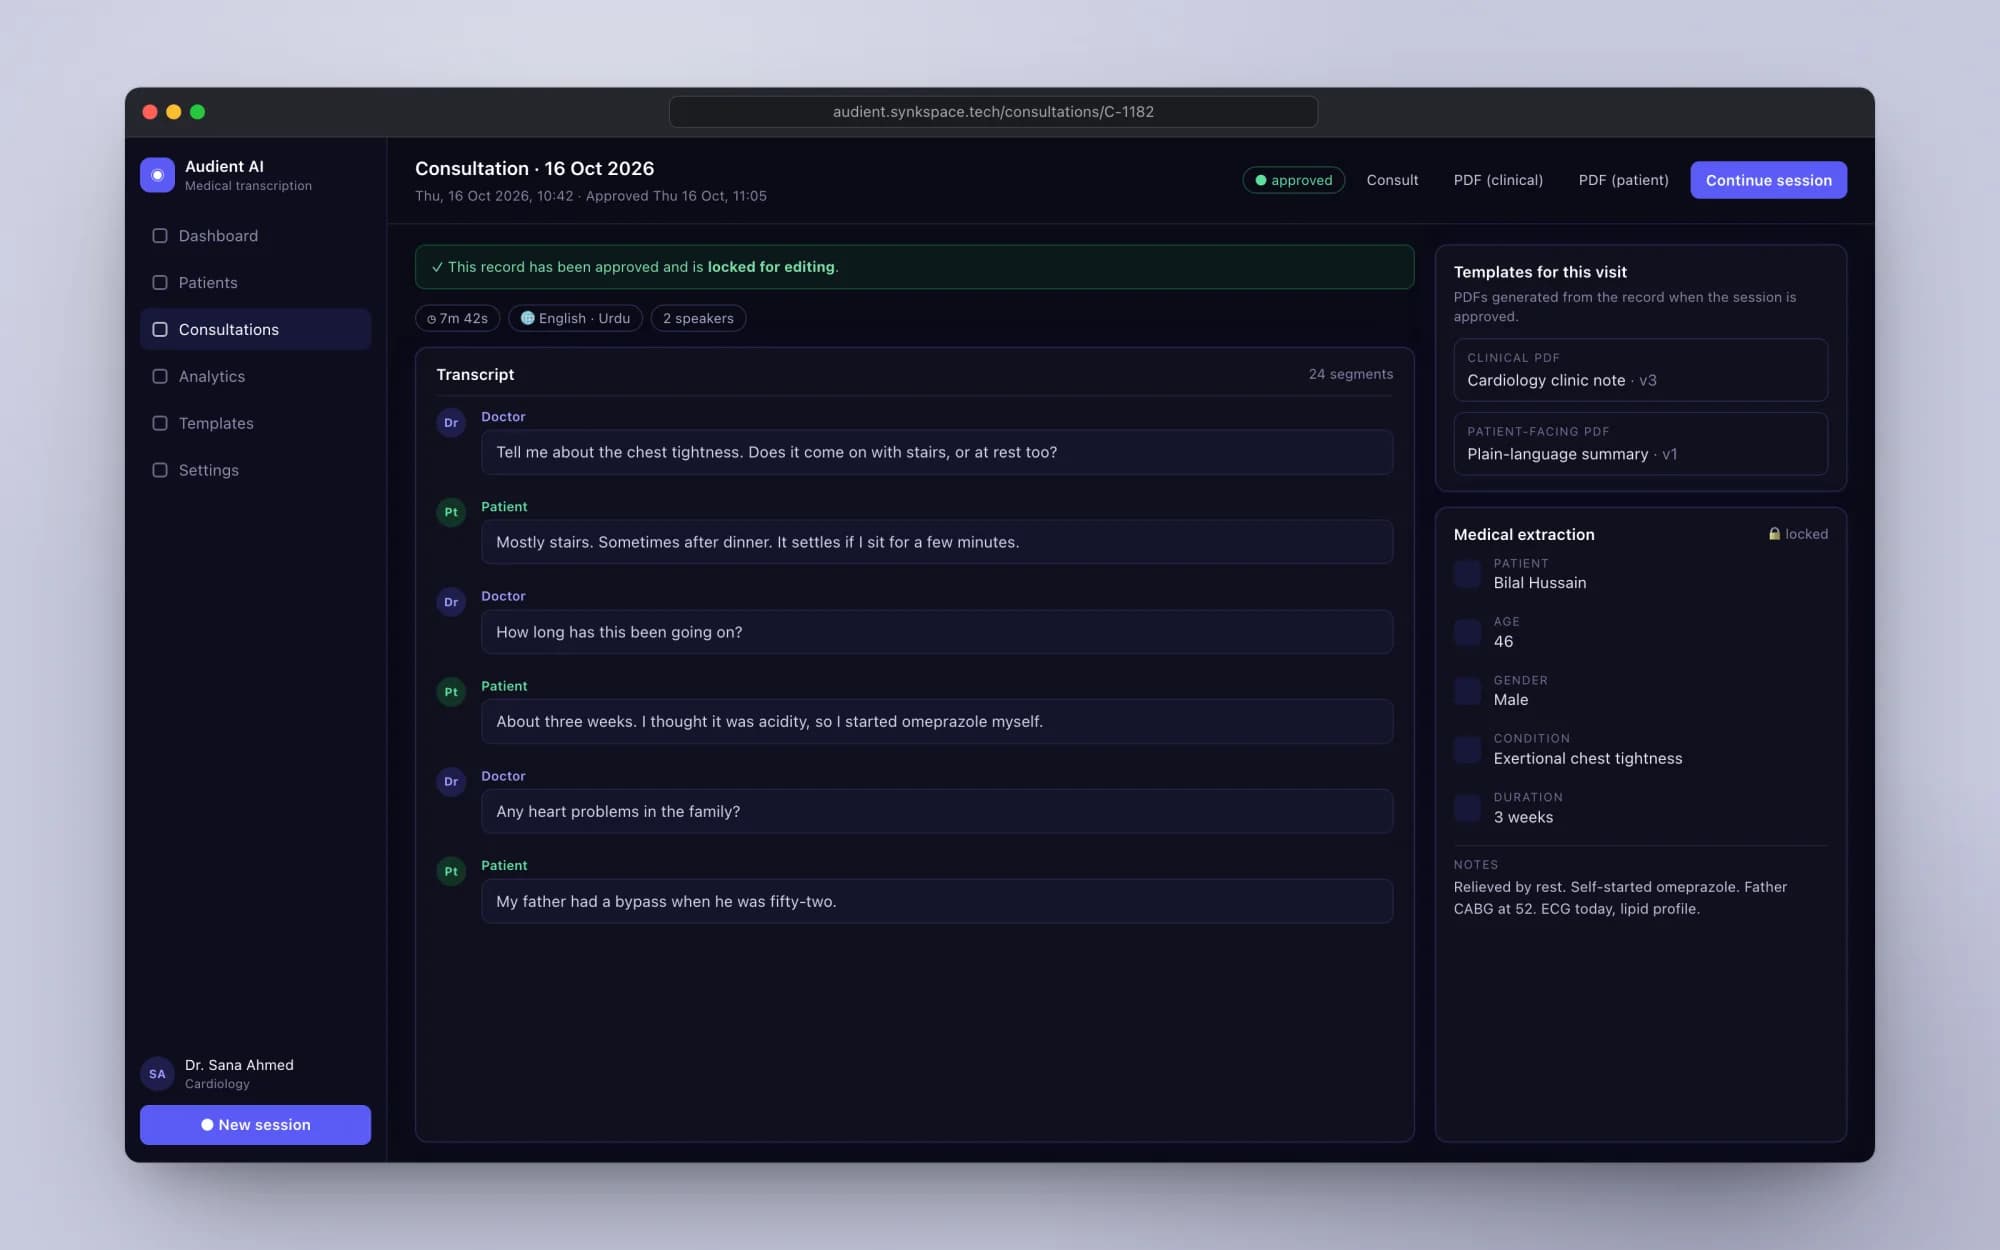
A live medical transcription platform. One microphone, two speakers: the conversation becomes a structured clinical record in real time, then a branded PDF the clinician approves and locks.
- Sector
- Healthcare
- Our role
- Product design, speech AI pipeline, full-stack build, cloud deployment
- Capabilities
- AI & agents · Platforms
- Status
- Delivered
The challenge
Doctors were spending their day typing instead of treating.
Clinicians lose a large share of their day to writing notes. Audient listens to the consultation and drafts the record as it happens, leaving the clinician to review instead of type.
What made it hard
- 01
Two voices, one channel
A single microphone stream has to be attributed to doctor or patient, turn by turn, without asking anyone to label it.
- 02
Latency is the product
Notes only help if they form during the visit, so transcription and extraction must run incrementally, not as a batch job afterwards.
- 03
Clinical-grade output
Free text is not a record. Every field must be structured, validated and gated behind a clinician sign-off.
The approach
A streaming pipeline that drafts the record while the conversation is still happening.
Audio is chunked in the browser and pushed over a WebSocket. Whisper transcribes each chunk, an LLM attributes speakers and maintains a structured extraction of seven clinical fields, and the client re-renders as state changes. Approval is a hard state transition: once signed, the record is immutable and rendered to templated PDFs.
System map
- AI step
- Person in the loop
- Service or store
How it works
- 01
Stream
The browser sends short audio chunks over a socket while the conversation is still going.
- 02
Transcribe
Speech is transcribed every few seconds, so the transcript grows in front of the user.
- 03
Separate
A language model works out who is the doctor and who is the patient.
- 04
Extract
Seven clinical fields are pulled out and kept up to date as more is said.
- 05
Flag
Anything missing is surfaced while there is still time to ask.
- 06
Approve
The clinician approves and the record locks. Clinic templates turn it into a clinical PDF and a plain-language patient summary.
- 07
Oversee
Analytics show sessions, outcomes and languages; admins manage clinicians and access.
Key decisions
Three calls that made it clinically safe.
Decision 01
Streaming, not batch
Seeing the record form live builds trust and lets the clinician correct course mid-visit.
Decision 02
Small model for fields, large model for speakers
Each job gets the cheapest model that does it well, which keeps latency low.
Decision 03
A person always signs off
The system drafts. It never files a record on its own.
What shipped
A clinical scribe, from microphone to signed PDF.
Streaming transcription
Chunked audio over Socket.IO, transcribed every few seconds with Whisper.
Speaker attribution
An LLM pass separates doctor and patient turns from a single stream.
Structured extraction
Seven clinical fields extracted and incrementally updated as context grows.
Gap detection
Missing required fields surface live, while the clinician can still ask.
Immutable sign-off
Approval locks the record and renders clinical and patient-facing PDFs.
Admin and analytics
Session, language and outcome analytics, with role-based clinician access.
Architecture
A cross-section of the system.
Every layer, from what people touch down to where it runs, and the one job each layer does.
L1Interface
React+TypeScript
Live transcript and record view, re-rendered on every server event.
L2Real-time
Socket.IO
Bidirectional channel for audio chunks in and extraction state out.
L3Services
Flask
Session orchestration, template rendering and the approval state machine.
L4Intelligence
Whisper+Llama
Speech-to-text, then speaker attribution and structured field extraction.
L5Data
PostgreSQL
Sessions, records, templates and audit of every approval.
L6Infrastructure
Docker+AWS
Containerised services deployed to managed cloud infrastructure.
Our scope
Product design/Speech AI pipeline/LLM extraction/Real-time backend/Web application/Cloud deployment
Where it is now
Live in production, with a clinician signing every record.
Audient runs in production. Clinicians review instead of type, and nothing reaches the record without an explicit, logged approval.
Keep exploring
The next problem.
Up next · Finance & Trading
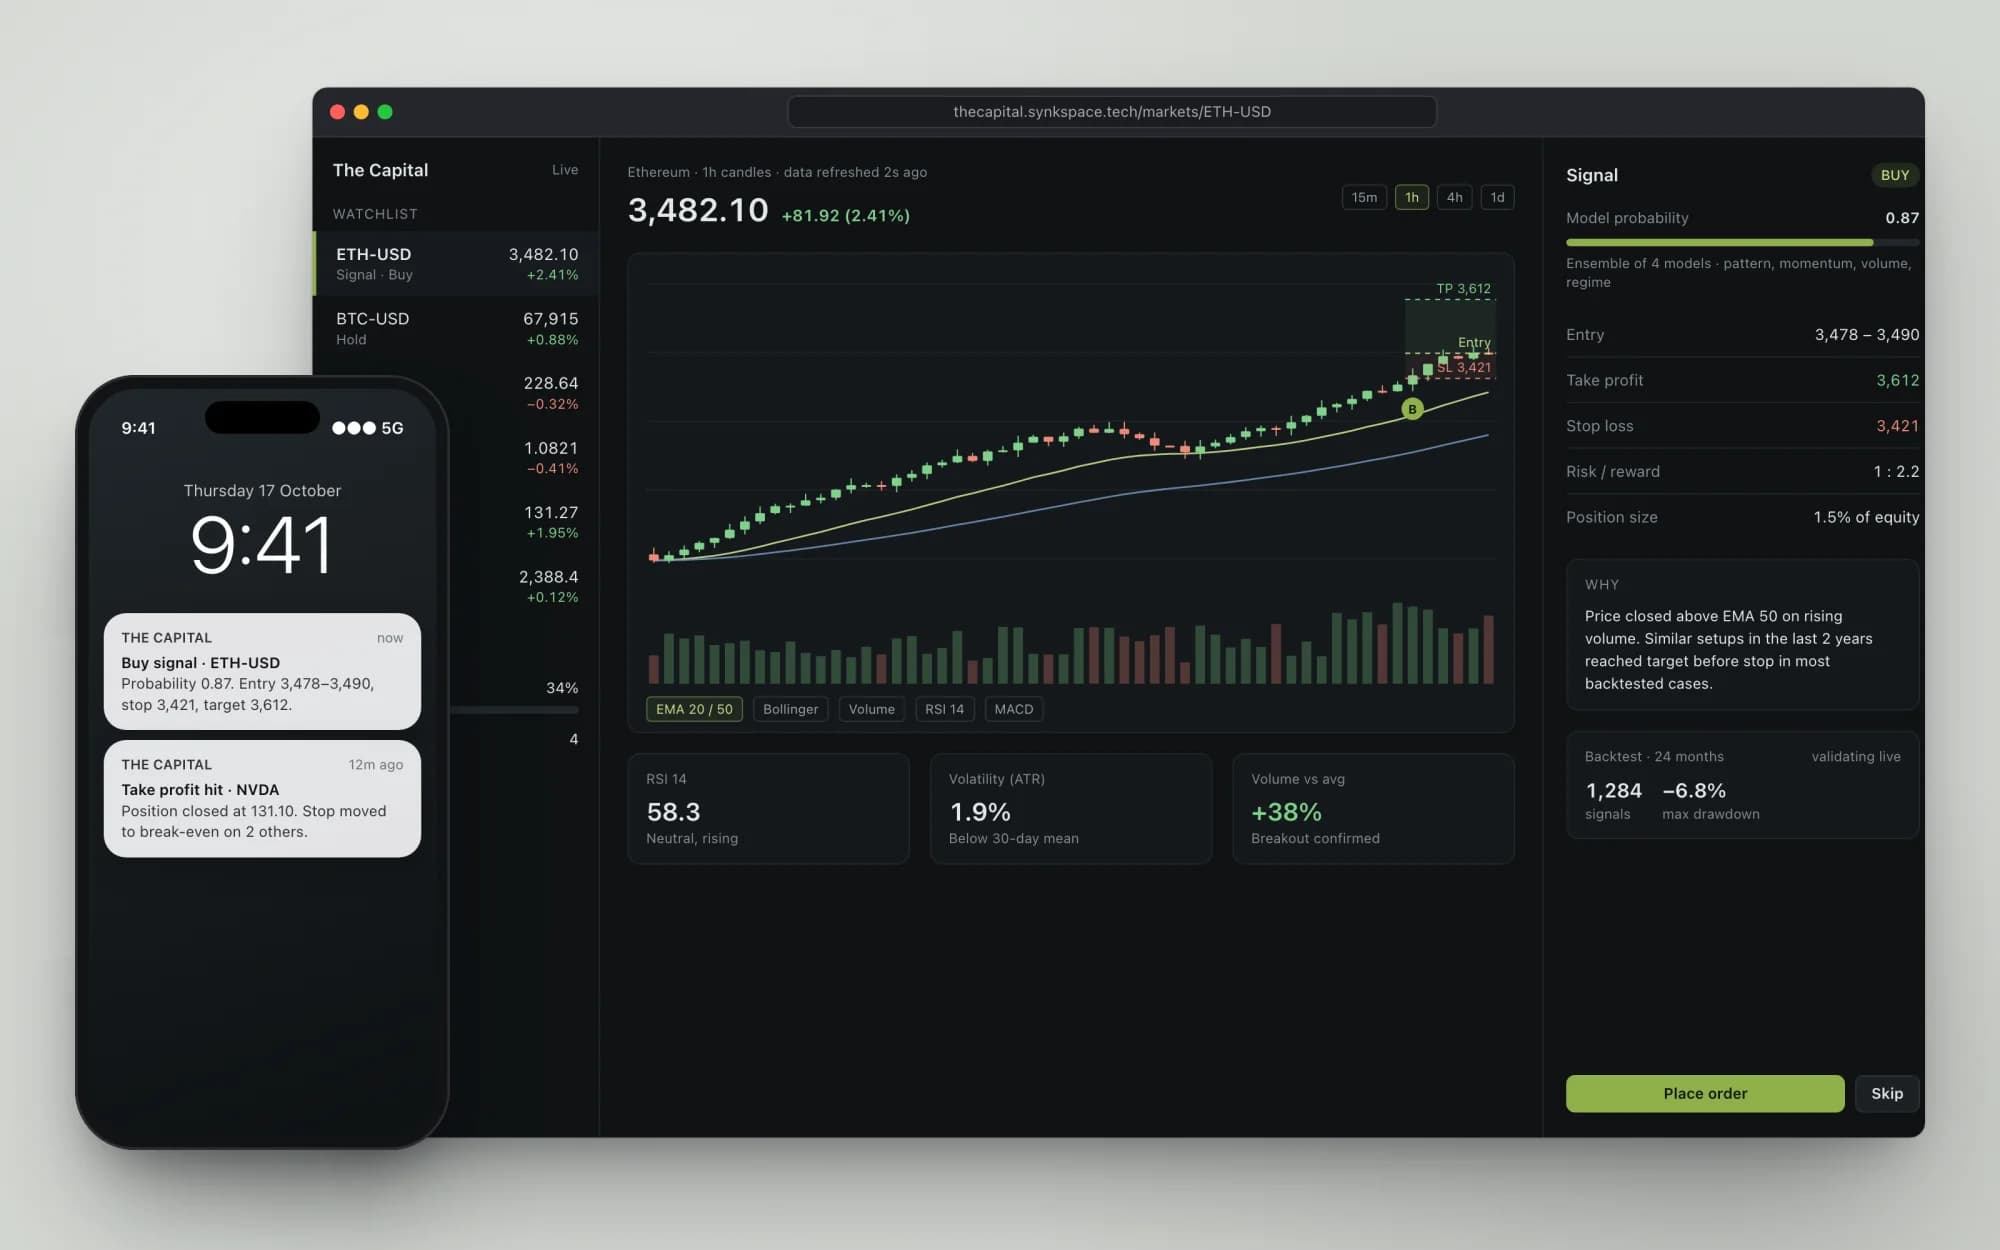
Markets punish inconsistency, and instinct is never consistent.
What made it hard
- 01Low signal-to-noise
- 02Probabilistic by nature
- 03Risk as a first-class output
See how we solved itThe Capital
 system map · hover for the product
Something like this in mind?
Tell us the problem. We will tell you honestly if we are the right team to solve it.